Understanding Cosine Similarity: From Math to Bare-Metal Vector Search
If you have spent any time working with Large Language Models, Retrieval-Augmented Generation (RAG), or vector databases, you have seen this term everywhere:
Cosine Similarity.
When you ask an AI assistant a question, the system converts your text into a list of numbers (an embedding), compares it against millions of stored vectors, and returns the most relevant chunks.
Almost every vector database tells you: “We use cosine similarity to rank semantic relevance.”
Most developers treat it as a black box function. You import a library, call similarity(a, b), and get a number between 0 and 1.
To be honest — that works fine when you are experimenting with a small demo.
But the moment you scale to millions of high-dimensional vectors, or try to build a low-latency cache for AI agents, understanding what cosine similarity actually does — and how to optimize it — becomes critical.
Let’s break down what cosine similarity really is from first principles, why it matters, and how to execute it on bare-metal hardware.
1. What is Cosine Similarity? #
At its core, cosine similarity measures the angle between two vectors, rather than the physical distance between their endpoints.
Imagine two arrows pointing from the origin (0, 0) in a multi-dimensional space.
- If the arrows point in the exact same direction, the angle between them is 0°.
- If the arrows point in completely perpendicular directions, the angle is 90°.
- If the arrows point in opposite directions, the angle is 180°.
In trigonometry, the cosine of an angle has very neat properties:
- $\cos(0^\circ) = 1.0$ (Identical direction)
- $\cos(90^\circ) = 0.0$ (Orthogonal / completely unrelated)
- $\cos(180^\circ) = -1.0$ (Diametrically opposed)
So cosine similarity gives us a clean score from -1.0 to 1.0 indicating how closely two vectors align in direction.
2. Why Not Euclidean Distance? The Document Length Trap #
Why do machine learning systems prefer the angle (cosine similarity) over straight-line distance (Euclidean distance)?
Consider this real-world scenario with text embeddings:
- Document A (Short Tweet): “PostgreSQL handles concurrent database locks efficiently.”
- Document B (Exhaustive Technical Article): A 5,000-word post explaining PostgreSQL concurrency, where the author repeats phrases about database locks, transactions, and queries dozens of times.
- Query Q: “How does Postgres manage locks?”
When an embedding model converts text into numbers, the direction of the vector captures the topic (PostgreSQL locks), while the magnitude (length of the vector) often reflects word frequency, text length, and density.
       Magnitude (Length)
          ^
          |             Document B (Long post, high magnitude)
          |            /
          |           /
          |          /
          |         /  <- Same direction (angle θ ≈ 0°)
          |        /
          |       * Document A (Short tweet, small magnitude)
          |      /
          |     /
          |    * Query Q
+----------------------------------->Look at what happens under both metrics:
Euclidean Distance ($L_2$ Distance) #
Euclidean distance measures the physical distance between the tips of the arrows:
$$d(A, B) = \sqrt{\sum (A_i - B_i)^2}$$Because Document B is long, its coordinates have much larger values. The straight-line distance between Query Q and Document B is enormous.
Euclidean distance would penalize Document B simply because it is longer, incorrectly ranking it as irrelevant!
Cosine Similarity #
Cosine similarity completely ignores the length of the arrows. It only cares about the angle $\theta$:
Because Document A, Document B, and Query Q all point in almost the exact same direction, $\theta \approx 0^\circ$, meaning:
$$\cos(\theta) \approx 1.0$$Cosine similarity recognizes that both documents are talking about the exact same topic, regardless of word count.
3. The Math: How It Is Calculated #
Mathematically, cosine similarity is defined as the inner dot product of two vectors divided by the product of their Euclidean lengths (magnitudes):
$$\text{Cosine Similarity}(A, B) = \frac{A \cdot B}{\|A\| \|B\|} = \frac{\sum_{i=1}^{n} A_i B_i}{\sqrt{\sum_{i=1}^{n} A_i^2} \sqrt{\sum_{i=1}^{n} B_i^2}}$$Let’s walk through a concrete numerical example with 2D vectors:
- Vector $A = [3, 4]$
- Vector $B = [6, 8]$
Notice that Vector $B$ is simply twice as long as Vector $A$, but points in the exact same direction.
Step 1: Calculate the Dot Product ($A \cdot B$) #
$$A \cdot B = (3 \times 6) + (4 \times 8) = 18 + 32 = 50$$Step 2: Calculate the Magnitude of $A$ ($\|A\|$) #
$$\|A\| = \sqrt{3^2 + 4^2} = \sqrt{9 + 16} = \sqrt{25} = 5$$Step 3: Calculate the Magnitude of $B$ ($\|B\|$) #
$$\|B\| = \sqrt{6^2 + 8^2} = \sqrt{36 + 64} = \sqrt{100} = 10$$Step 4: Divide Dot Product by Combined Magnitudes #
$$\text{CosineSim}(A, B) = \frac{50}{5 \times 10} = \frac{50}{50} = 1.0$$The result is 1.0 — a perfect match, exactly as expected.
4. The Performance Bottleneck in Vector Search #
In practice, embeddings don’t have 2 dimensions. Modern embedding models produce vectors with 384, 768, or 1,536 dimensions.
And in a vector database, you don’t compare two vectors once. You compare one query vector against hundreds of thousands or millions of stored vectors.
Let’s look at the math required for a single search across 100,000 vectors with 768 dimensions:
- 76.8 million multiplications
- 76.8 million additions
- 100,000 square root operations ($\sqrt{\sum V_i^2}$)
- 100,000 floating-point divisions
On modern CPUs, additions and multiplications are fast. But square roots and floating-point divisions are expensive:
- A floating-point multiply-accumulate takes ~1 to 4 CPU cycles.
- A floating-point square root (
sqrt) or division (div) can take 15 to 40 CPU cycles and easily stalls processor execution pipelines.
If your vector database computes square roots and divisions for every vector candidate on every query, your search latency will degrade quickly.
5. The Ingestion Trick: Pre-Normalized Unit Vectors #
How do high-performance systems solve this?
With a simple mathematical identity: $L_2$ Unit Normalization.
Before storing any vector into memory, divide the vector by its own magnitude:
$$\hat{V} = \frac{V}{\|V\|}$$After this transformation, the length of $\hat{V}$ is guaranteed to be exactly 1.0:
$$\|\hat{V}\| = 1.0$$When a user query arrives, the query vector is normalized once:
$$\|\hat{Q}\| = 1.0$$Now, look at what happens to the cosine similarity equation:
$$\text{CosineSim}(\hat{Q}, \hat{V}) = \frac{\hat{Q} \cdot \hat{V}}{\|\hat{Q}\| \times \|\hat{V}\|} = \frac{\hat{Q} \cdot \hat{V}}{1.0 \times 1.0} = \hat{Q} \cdot \hat{V}$$The denominator completely disappears.
Cosine similarity simplifies to a pure inner dot product:
$$\text{CosineSim}(\hat{Q}, \hat{V}) = \sum_{i=1}^{n} \hat{Q}_i \times \hat{V}_i$$- Zero square roots during search.
- Zero floating-point divisions during search.
- Only fused multiply-adds (FMA).
By moving the normalization cost to write time (ingestion), query-time search becomes orders of magnitude faster.
6. Going to Bare Metal: SIMD Vectorization #
Once cosine similarity is reduced to a pure dot product, how fast can a CPU actually compute it?
If you write a standard loop in Python or C:
float dot = 0.0f;
for (int i = 0; i < 384; i++) {
    dot += q[i] * v[i];
}The CPU processes one float at a time (scalar execution).
Modern processors have specialized SIMD (Single Instruction, Multiple Data) execution units:
- ARM NEON (Apple Silicon, AWS Graviton): 128-bit vector registers that process four 32-bit floats simultaneously.
- x86_64 AVX2 + FMA (Intel / AMD): 256-bit vector registers that process eight 32-bit floats in a single clock cycle using Fused Multiply-Add (
_mm256_fmadd_ps).
With 4-way loop unrolling across multiple accumulator registers, a modern CPU can compute:
- 16 floats per loop iteration on ARM NEON
- 32 floats per loop iteration on AVX2
Here is what that looks like in bare-metal Rust:
// AVX2 + FMA bare-metal inner dot product (x86_64)
#[target_feature(enable = "avx2,fma")]
unsafe fn dot_product_avx2(a: &[f32], b: &[f32]) -> f32 {
    let mut acc0 = _mm256_setzero_ps();
    let mut acc1 = _mm256_setzero_ps();

    // Process 16 floats per iteration using 2 accumulators
    let chunks = a.chunks_exact(16).zip(b.chunks_exact(16));
    for (chunk_a, chunk_b) in chunks {
        let va0 = _mm256_loadu_ps(chunk_a.as_ptr());
        let vb0 = _mm256_loadu_ps(chunk_b.as_ptr());
        acc0 = _mm256_fmadd_ps(va0, vb0, acc0);

        let va1 = _mm256_loadu_ps(chunk_a.as_ptr().add(8));
        let vb1 = _mm256_loadu_ps(chunk_b.as_ptr().add(8));
        acc1 = _mm256_fmadd_ps(va1, vb1, acc1);
    }

    // Sum accumulators down to a single float
    let sum = _mm256_add_ps(acc0, acc1);
    hsum256_ps(sum)
}At this level:
- A full 384-dimensional vector comparison executes in under 150 nanoseconds.
- A CPU core can scan over 6 million vector comparisons per second.
7. Putting It Into Practice: How KacheDB Implements This #
Theory is great, but real systems need more than raw vector math.
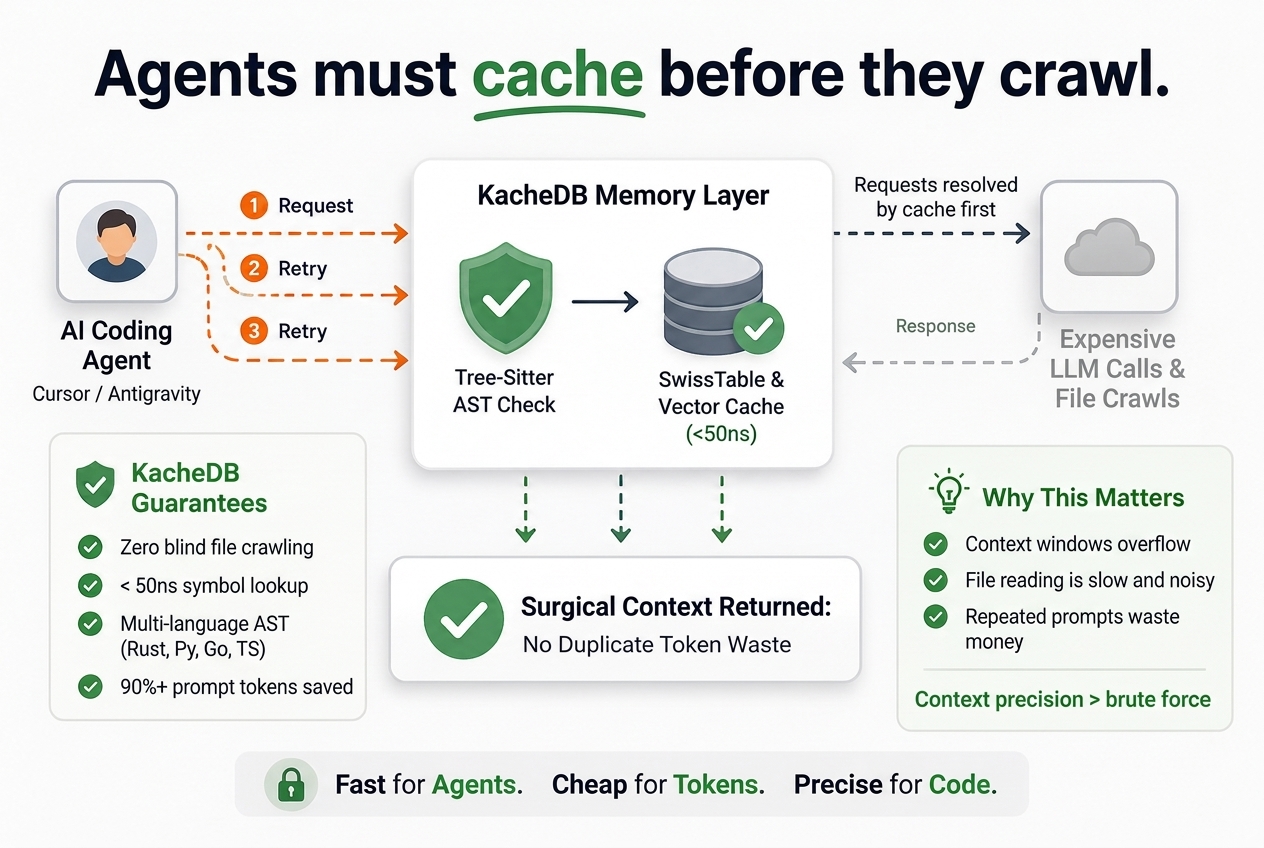
In KacheDB — an open-source, ultra-low latency semantic cache and vector memory engine for AI coding agents — this exact pipeline is implemented directly in Rust.
AI coding assistants (like Cursor, Claude Code, or Antigravity) constantly scan large workspaces. If an agent has to crawl 500 files and re-embed code snippets repeatedly, it wastes minutes of developer time and burns millions of LLM tokens.
To solve this, KacheDB uses a 2-Tier Hybrid Retrieval Engine:
Tier 1: L1 SwissTable Exact Cache (< 50 ns) #
Before touching any vector math or neural embeddings, KacheDB checks an in-memory SwissTable (Google’s SIMD hash table). If the prompt or code symbol has an exact alias match, it returns the result in less than 50 nanoseconds with 0 ms embedding latency.
Tier 2: 64-Bit Bitmask Pre-Filtering + L2 SIMD Vector Scan #
If an exact match misses:
- Every vector entry has a 64-bit integer tag bitmask. KacheDB checks tag filters with a single bitwise
AND(candidate_mask & query_mask != 0) in 1 CPU cycle, instantly skipping irrelevant workspaces or files. - For matching candidates, Rust SIMD kernels compute pre-normalized cosine dot products in parallel.
- A two-stage adaptive relaxation policy automatically steps down the threshold if short code symbols require broader semantic discovery.
Explore the implementation: If you are curious to see how the SIMD kernels, pre-normalized vector index, and SwissTable cache work together under the hood, the entire codebase is open-source.
Check out the repository on GitHub: vubon/kachedb
You can clone it, inspect the Rust crates (
crates/kachedb-vector), run the Criterion benchmarks, and experiment with the MCP server (kachedb-mcp).
Key Takeaways #
- Cosine similarity measures angle, not magnitude. This prevents document length from skewing search results.
- Raw cosine similarity is computationally expensive. Calculating square roots and floating-point divisions on millions of vectors stalls CPU execution pipelines.
- Pre-normalize your vectors at ingestion. By ensuring $\|V\|_2 = 1.0$, cosine similarity simplifies to a clean, division-free inner dot product ($Q \cdot V$).
- Use SIMD for high throughput. ARM NEON and AVX2+FMA process up to 32 floats per clock cycle, bringing 384-d vector comparisons down to < 150 nanoseconds.
- Combine exact caching with semantic search. Even the fastest vector math cannot beat a 50 ns hash table lookup. Cache first, search second.